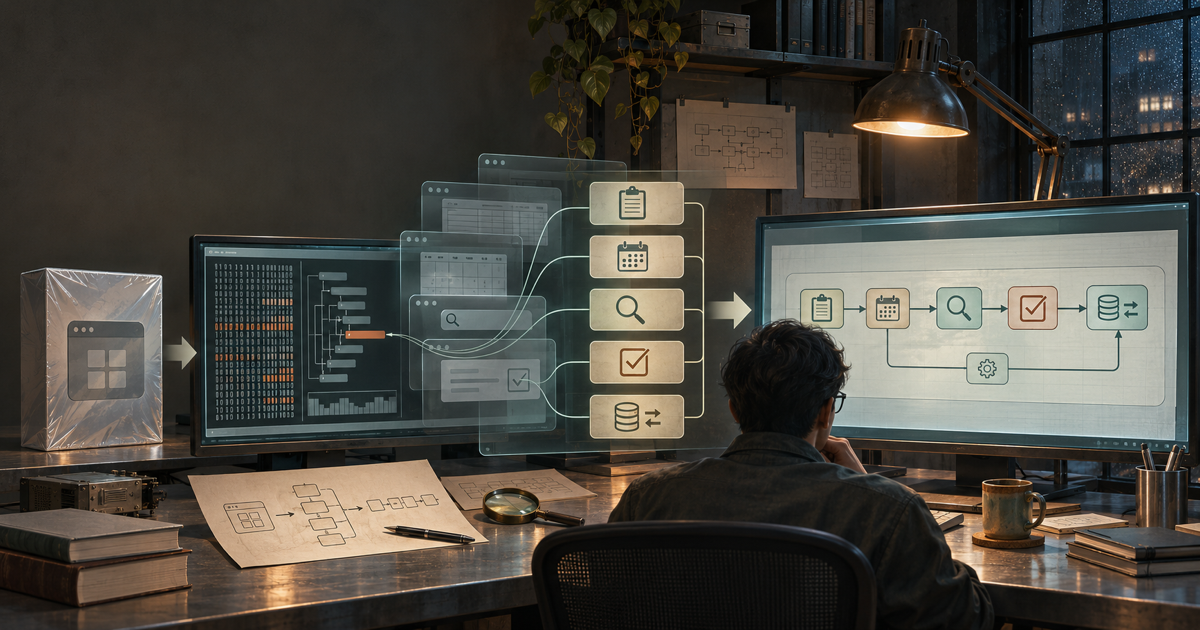
The application on the left is no longer a sealed product. Its observable behaviors become evidence, reusable capabilities, and a new operational workflow. Illustration generated for this essay.
A package on the workbench
A sealed software box sits under a desk lamp. On one screen, a disassembler exposes functions, calls, and strings. On the other, the useful part has already escaped the package: a clipboard bridge, a scheduling rule, a search interaction, an approval path.
The scene raises a question I kept returning to while developing Semantic Studio:
What if software is not the durable product? What if it is the temporary implementation of a job that needs doing?
The premise behind Semantic Studio is to represent intent before implementation: the workflow, decisions, data, constraints, effects, and interface. Software can then be generated as one executable projection of that representation.
Then REA—Reverse Engineer Anything—arrived and made the opposite journey executable. It starts with existing software, gathers evidence about behavior, and gives an agent enough structure to explain or reconstruct an authorized capability.
The obvious story is reverse engineering. The more consequential story is what happens to the boundary around an application.
The attention signal
On November 4, 2026, the official REA repository displayed roughly 430,800 stars and 107,100 forks. Those numbers will keep moving. They measure attention and copying activity, not active deployments, reliable reconstructions, or lawful use.
Still, the scale is difficult to dismiss. REA’s proposition is unusually direct: connect a coding agent to inspection systems, ask how a feature works, demand the evidence, and build a version for your own project. Its documented providers include Hopper, Ghidra, IDA, and Kuna for native analysis, while other paths cover JavaScript, Electron, .NET, Android, websites, captured traffic, and more.
The repository’s own description keeps the sequence honest:
inspect the target
→ trace relevant code and behavior
→ return findings with evidence and limitations
→ explain, implement, and test
REA does not make reverse engineering disappear. Ghidra still decompiles. Hopper still disassembles. JADX still reads Android packages. The agent sits above those instruments and turns their output into a question a builder actually asks:
Which behavior matters here, and what evidence explains it?
That shift—from application to behavior—is the real signal.
We built software around packages
Most software still arrives with the economic shape of a physical product.
You need invoicing, so you buy accounting software. You need project planning, so you license a project-management platform. You need one automation inside a CRM, so the company buys seats for an entire suite. Hundreds of capabilities travel together because producing a custom application once required a team, a budget, and months of integration work.
The package solved a manufacturing constraint:
high creation cost
→ standardized product
→ many customers
→ users adapt to the package
AI-assisted generation lowers the first cost. REA applies pressure from the other side. It treats the package as something that can be inspected for one useful behavior.
The emerging question is no longer:
Which application should I adopt?
It is:
Which capability does this job require, and where should that capability live?
If that question becomes normal, the application stops being the smallest useful commercial or technical unit.
The Notion example matters because it is small
REA’s official showcase list includes a trace of Notion’s Electron clipboard bridge. The investigation follows a renderer API through preload and IPC into the main process, then inspects the rich clipboard format.
That is quieter than cloning an application. It is also more revealing.
The useful unit is not “Notion.” It is one observable behavior: how a particular clipboard path crosses process boundaries. A builder can inspect the evidence, understand the mechanism, and decide whether a lawful, independently implemented version belongs in another workflow.
Traditional software thinking says:
I need that product.
Capability thinking says:
I need that operation, under these constraints, inside this workflow.
Search, formatting, authentication, scheduling, visualization, data reconciliation, approval logic, and agent routing can each become composable parts. The package boundary loses some of its authority.
REA performs evidence-backed semantic extraction
At the machine level, REA can return pseudocode, assembly, modules, imports, routes, IPC channels, requests, responses, and runtime observations. None of those artifacts is the user’s goal.
The agent has to turn this:
binary regions
source fragments
runtime observations
network calls
application state
into this:
capability
preconditions
state transitions
constraints
effects
evidence
unknowns
I call that step semantic extraction. It does not mean the agent has discovered the author’s original intent. That claim would be too strong. It means the agent has formed a testable explanation of observed behavior and linked that explanation to evidence.
The distinction matters. A function at address 0x1042AF30 is an implementation fact. “A copied table becomes structured rich text after crossing an IPC boundary” is a behavioral claim. A useful system keeps the chain between them visible.
Semantic Studio starts from the other end
REA begins with software and works backward. Semantic Studio begins with proposed intent and works forward.
flowchart LR
    A["Existing software"] --> B["Code and runtime evidence"]
    B --> C["Behavioral model"]
    C --> D["Reconstructed capability"]
flowchart LR
    E["Proposed intent"] --> F["Semantic system model"]
    F --> G["Workflow, data, decisions, constraints"]
    G --> H["Generated implementation"]
Put the two directions together:
flowchart LR
    A["Proposed intent"] <--> B["Semantic representation"]
    B <--> C["Software"]
    C <--> D["Observed runtime behavior"]
Source code becomes one representation among several. Tests are another. Runtime traces are another. The interface is another. The primary question moves from “What files should we write?” to “What should this system do, what must it never do, and what evidence would show the difference?”
This does not eliminate programming. It changes where programming sits in the stack.
Generated software is already becoming ordinary
REA is not an isolated event. Other systems are moving from meaning toward software.
Lovable reported in August 2026 that people had created more than 60 million projects and that Lovable-built applications received more than 900 million visits each month. By October 29, the company reported more than 70 million projects and 1.2 million new projects per week. These are vendor-reported platform figures, not an independent census of durable production systems.
The examples are still instructive. Lovable describes teams creating CRMs, finance tools, internal hubs, approval flows, dashboards, storefronts, and operational applications. The person nearest the problem can increasingly produce the tool without first turning the need into a software-procurement exercise.
Replit’s ChatGPT integration makes the transition almost literal. Its example prompt asks for a restaurant bill splitter. The application appears in the conversation; subsequent instructions add interface changes or a payment form; the same application can then be published.
Nobody begins by shopping for bill-splitting software. A requirement exists. Software appears around it.
That is software behaving like a utility.
SaaS does not vanish; value moves
In a server room, the screens are the inexpensive part. The costly machinery sits behind them: identity, permissions, databases, audit trails, availability, regulatory controls, maintenance, incident response, and shared organizational state.
Cheap implementation does not make those burdens disappear.
Salesforce is not valuable because someone drew CRM screens. Stripe is not valuable because it exposes a payment form. Their durable value includes infrastructure, trust, operating history, distribution, integrations, risk controls, and embedded workflows.
The vulnerable layer sits between those assets:
- generic feature bundles;
- thin workflows sold as separate products;
- interfaces around commodity operations;
- minor variations of tools a team can now generate or absorb elsewhere.
The moat does not vanish. It moves away from implementation alone and toward data, distribution, network effects, institutional trust, regulated access, physical infrastructure, and the accumulated knowledge of operating a system safely.
Capability extraction has a hard legal boundary
A disassembler on the desk is not a blank permission slip.
REA’s responsible-use statement limits the project’s intended scope to lawful analysis such as authorized security research, interoperability, preservation, debugging, and auditing software the user owns or is authorized to inspect. It explicitly rejects copying proprietary software or protected code and assets, bypassing access controls, defeating license checks, and other unauthorized activity.
The same boundary applies to this essay. “Extract a capability” means forming an evidence-backed understanding and implementing behavior only where authorization, licenses, contracts, intellectual-property law, and terms permit it. Public availability of an application does not establish permission to inspect or reproduce every part of it.
This constraint is not peripheral. If capability-level software is going to become normal inside companies, provenance and authorization have to travel with the capability:
| Capability record | Question it must answer |
|---|---|
| Origin | Was this generated from requirements, an open specification, owned software, or an authorized inspection? |
| Evidence | Which observations support the behavioral model? |
| Rights | Which licenses, permissions, and contractual limits apply? |
| Independence | Which code and assets were written independently? |
| Verification | Which tests compare the new behavior with the permitted target? |
| Unknowns | Which conclusions remain heuristic or incomplete? |
Without that record, “software as utility” can collapse into untraceable copying.
Perplexity turning REA into a skill is the transition to watch
In October, Perplexity announced a Reverse Engineer skill for Computer built on the open-source REA framework. The published examples move through three steps: inspect an authorized application, reconstruct a workflow, and compare the reconstruction with the original behavior.
The packaging is important. A specialist tool becomes a skill inside a general computer agent.
Today, the instruction is:
Inspect this application and explain its export workflow.
The next version may be:
I like how this system handles scheduling. Build an authorized equivalent around our calendar, CRM, and warehouse data. Give managers approval rights. Retire it when the project ends.
That final request does not describe a product category. It describes an operational need and a lifecycle.
The missing middle layer
Natural-language coding tools still keep source files near the center. A person describes a change, the agent edits code, and the person inspects the result. The abstraction leaks whenever a requirement, exception, authority, or evidence rule fails to survive the translation.
Prompts are too vague to become the durable record. Source code is too implementation-specific. Diagrams are usually non-executable. Conventional process models rarely express modern agent behavior, uncertainty, and approval cleanly.
REA and generative builders expose a gap:
software → meaning
meaning → software
What sits between the arrows should be a formal, inspectable representation of what the system is meant to do.
Call it a semantic model, executable intent, or an intermediate representation for software. The name matters less than its obligations:
- Humans can inspect and edit outcomes, constraints, exceptions, data, and authority.
- The model compiles into deterministic, versioned execution artifacts.
- Tests and simulations derive from the same representation.
- Runtime traces map back to the claims they support or contradict.
- A semantic diff shows the operational consequence of a change.
- Authorization and provenance remain attached to imported capabilities.
This is the larger Semantic Studio ambition.
A research program, not a product claim
The next useful work is not another demo that produces a polished interface. It is a set of comparative trials.
| Partner | Testable artifact |
|---|---|
| Programming-languages or model-driven engineering researcher | A typed intent representation and deterministic compilation contract |
| Reverse-engineering or software-preservation team | An evidence schema connecting low-level observations to behavioral claims |
| Enterprise platform or internal-tools team | A real workflow rebuilt from intent, then changed through semantic diffs |
| Security, legal, or open-source specialist | A rights-and-provenance model that survives capability reuse |
| Human-computer interaction researcher | A study of whether domain owners catch more consequential errors in an intent view than in tickets or generated code |
The central comparison is concrete. Give matched teams the same operational change. One team works through tickets, prompts, and source review. The other edits an intent model, sees generated tests and a behavioral diff, and approves a deterministic build. Measure correction time, escaped policy violations, reviewer agreement, and recovery from runtime mismatch.
If the semantic layer merely adds another document, the idea has failed.
A narrow bridge to Aegis
This essay is about software architecture, not AI governance. I plan to carry one part into Aegis: a consequential agent action should be traceable from approved intent through implementation evidence to observed effect. REA’s evidence discipline and Semantic Studio’s executable-intent layer could make that chain more inspectable without turning this article into an Aegis argument.
More software, fewer permanent products
At the end of the project, the temporary interface can disappear. The data remains in governed systems. The decision record stays. The capability can be regenerated when the next team needs it.
That future contains more software, not less:
- personal applications;
- company-specific tools;
- interfaces used by five people;
- applications generated for one project;
- workflows rebuilt when their constraints change;
- software deleted after three days.
The half-life becomes shorter because implementation becomes easier to replace.
REA’s popularity does not prove that this architecture will win. Lovable’s project counts do not prove that generated applications are reliable. Replit’s conversational demo does not remove the need for engineering. These are signals, not validation.
But they point in the same direction. Existing applications are becoming searchable sources of authorized behavior. New applications can emerge directly from a described need. The missing layer is an inspectable model that can travel between those directions without losing constraints, evidence, or accountability.
We spent decades teaching people to navigate the structure of software: products, menus, file formats, APIs, and codebases. The next abstraction may reverse the relationship.
Describe the job. Inspect the evidence. Preserve the constraints. Let software take the form the work requires.
References
- REA, official repository and documentation.
- REA, responsible-use disclaimer.
- Perplexity, Reverse Engineer skill announcement.
- Lovable, August 2026 Series C and platform-usage announcement.
- Lovable, October 2026 London announcement and updated project count.
- Replit, “Now You Can Build with Replit in ChatGPT”.
Related essays
- The End of Programming as the Primary Interface develops the intent-graph and observed-intent architecture in greater technical detail.
- From Proposed Intent to Observed Intent traces runtime evidence back into controlled model revision.
- Interaction-Derived Unpredictability examines how system behavior can emerge from interaction rather than a single opaque component.
After the last line
Comments & sharing
Agree, disagree, add context, or send this to someone who would have a take.
Share
Public thread
Comments are public and attached to this post through GitHub Discussions. Sign in with GitHub to join the thread.
Open public discussions